SemKV™ - Intelligent context optimization for AI Systems
High-quality semantic context optimized for edge intelligence, CPU-efficient AI systems, selective activation, token efficiency and scalable semantic infrastructure powered by the S3 architecture.
AI systems are drowning in context
Modern retrieval systems increasingly depend on larger context windows, reranking pipelines, GPU-heavy infrastructure, and excessive token activation to compensate for retrieval inefficiency.
AI systems are now spending enormous compute resources processing irrelevant tokens, duplicated structures, and low-signal semantic noise before useful information is even reached.
The challenge is no longer generating intelligence. The challenge is activating only what truly matters.
Stop Flooding Context Windows
Traditional retrieval systems over-activate context, increase token usage, and inflate inference cost. SemKV™ selectively activates only semantically relevant structures through the S3 architecture.
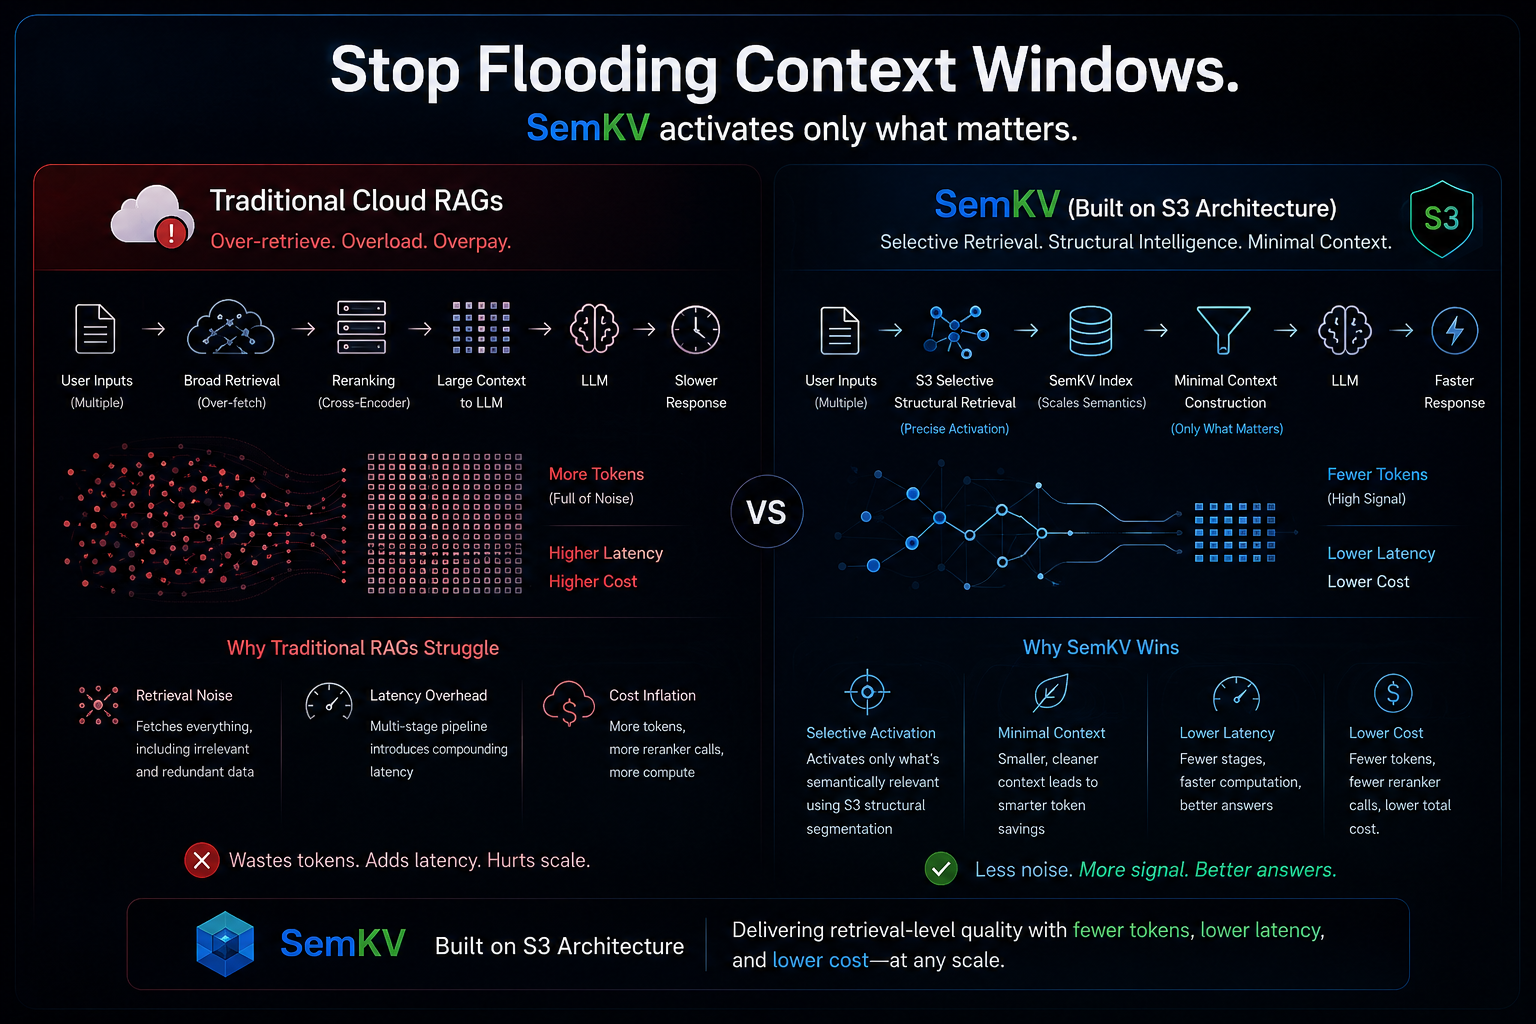
Traditional AI Retrieval
- • Over-fetches irrelevant context
- • Expands token consumption rapidly
- • Requires reranking overhead
- • Depends heavily on GPU infrastructure
- • Introduces latency compounding
SemKV™ Approach
- • Selective semantic activation
- • Minimal context construction
- • Lower token overhead
- • CPU and Edge optimized
- • Precision-first retrieval flow
Selective Structural Segmentation for Precise Semantic Activation
SemKV™ is powered by the S3 architecture — a semantic infrastructure pipeline that identifies, structures, indexes, and activates only semantically relevant information instead of flooding large context windows.
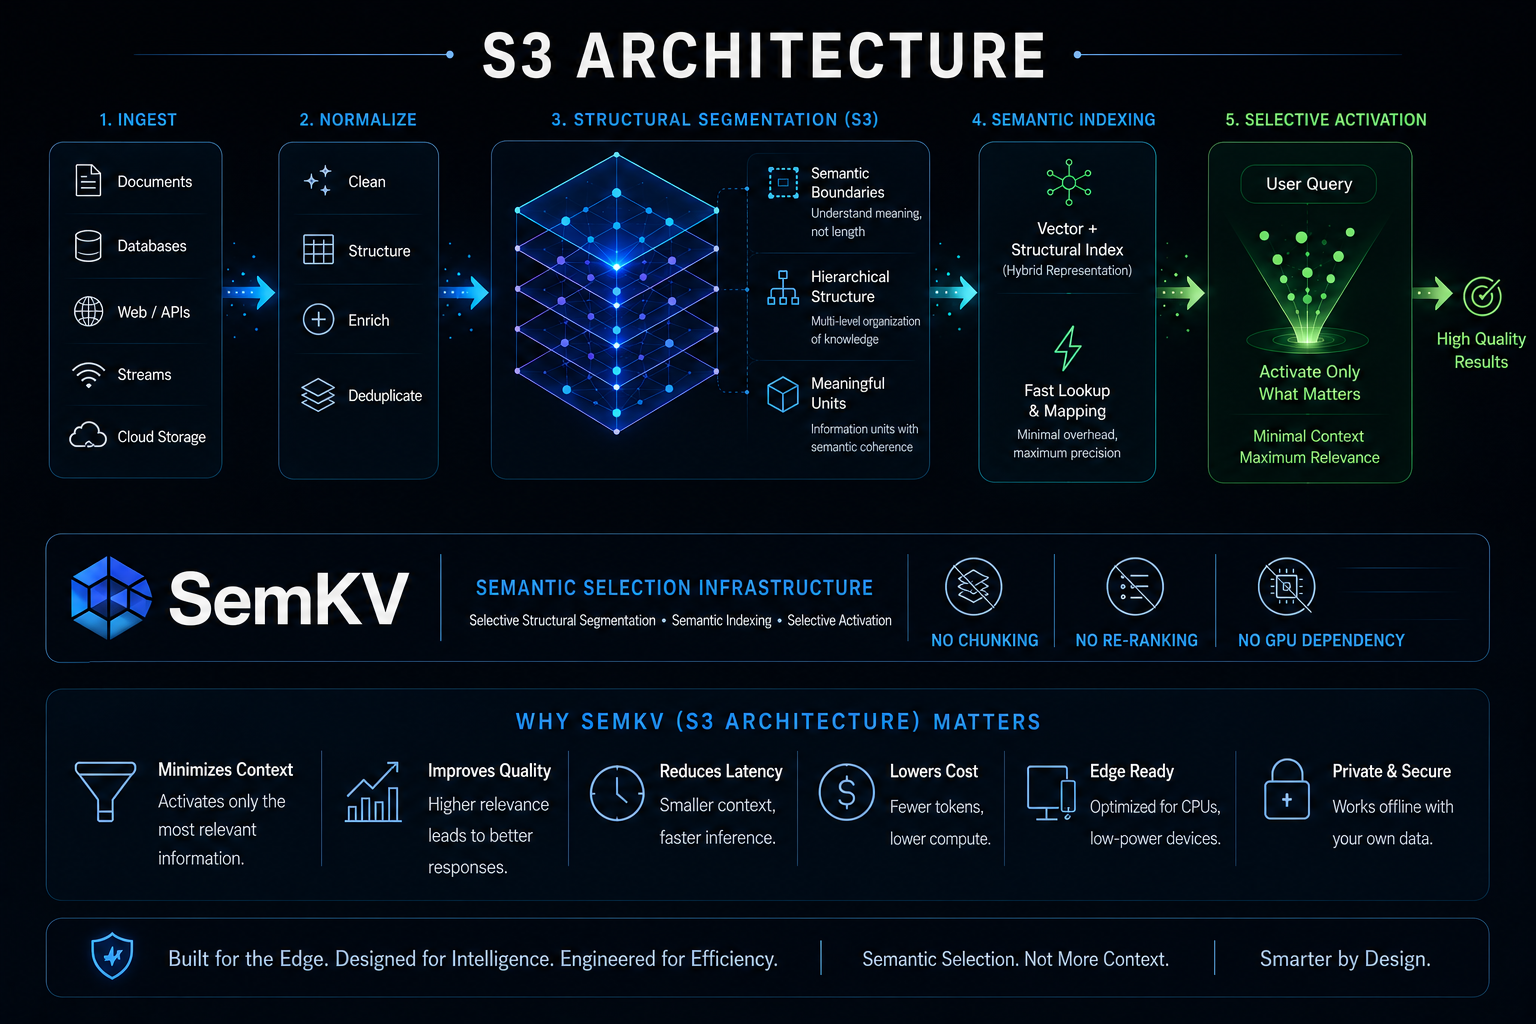
Precision selection for Edge AI systems
Scalable CPU-efficient semantic activation across cloud and edge environments. From edge devices and local AI systems to scalable distributed infrastructure, SemKV™ is built for selective intelligence instead of brute force context expansion.
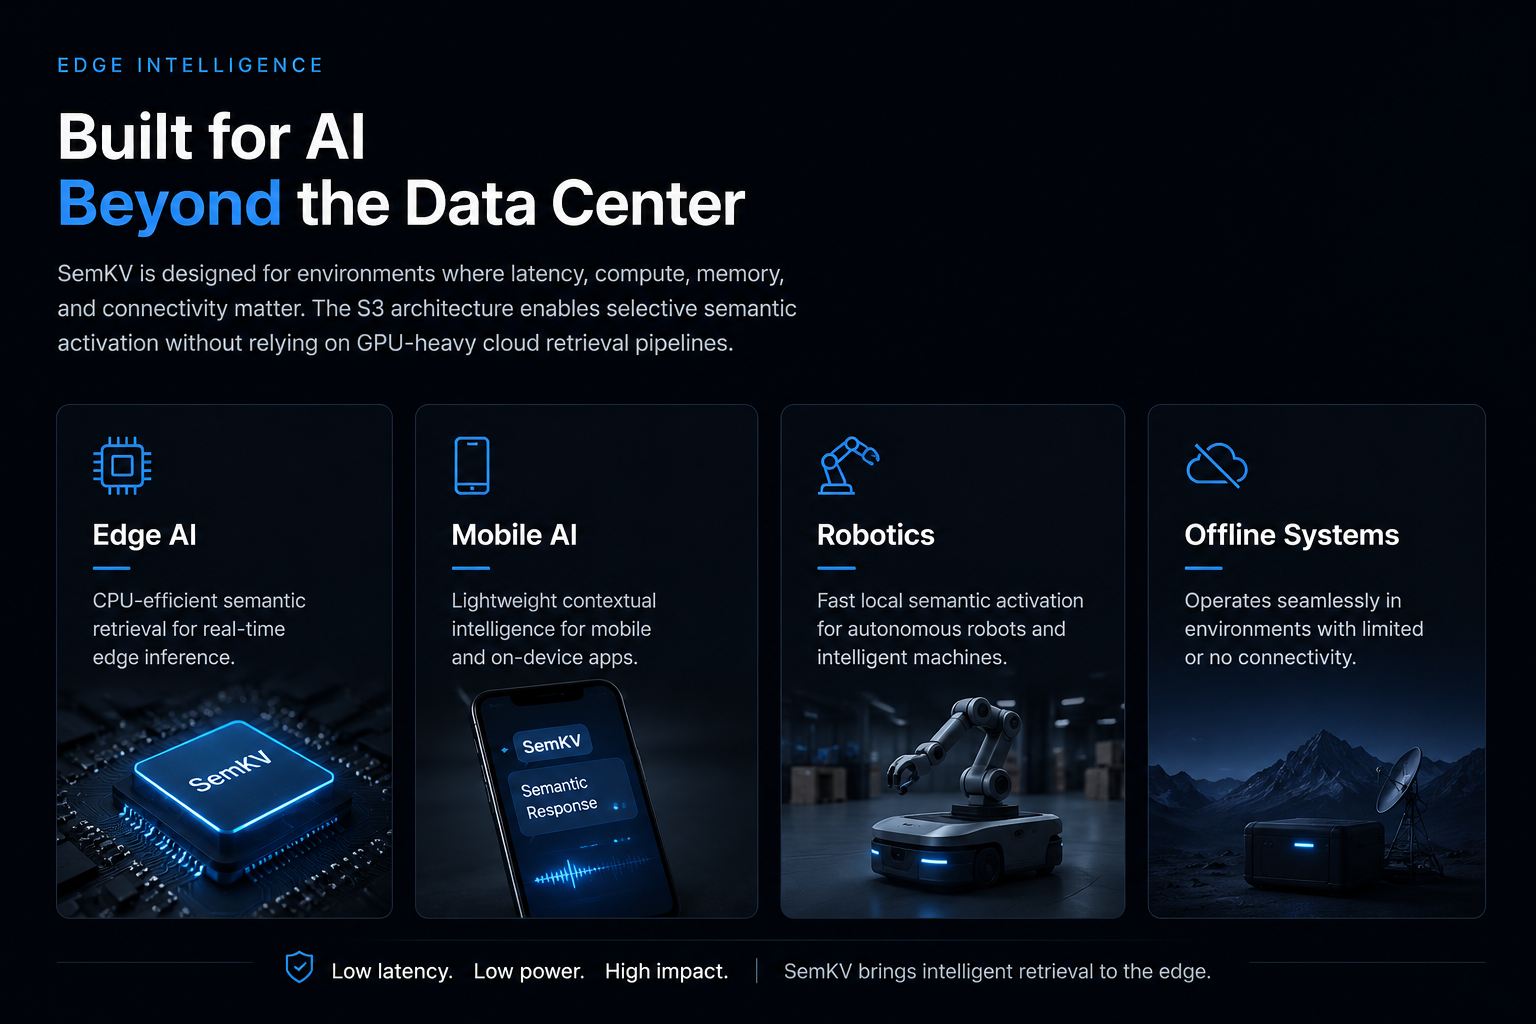
Edge-native by design. Intelligent by nature.
SemKV™ brings selective semantic intelligence to the edge — where compute efficiency, latency, and reliability matter most.
Measured for Efficiency. Built for Scale.
SemKV™ and the S3 architecture are designed to reduce unnecessary semantic activation, minimize token overhead, and improve retrieval precision across cloud and edge AI environments.
Our evaluation framework focuses on practical retrieval behavior including token efficiency, activation precision, latency characteristics, and scalable semantic selection performance.
Token Efficiency
Measures reduction in unnecessary context activation, semantic noise propagation, and excessive token expansion across retrieval pipelines.
Semantic Similarity
Measures the ability to retrieve semantically relevant information while preserving contextual meaning.
Latency Behavior
Tracks retrieval overhead, reranking dependency, activation latency, and response efficiency under scalable workloads.
TruthMetrics™
10-dimensional behavioral evaluation framework for measuring retrieval integrity, semantic fidelity, corruption visibility, and entropy survivability
Edge Compatibility(CPU Deployment)
Benchmarks CPU-efficient semantic retrieval behavior for constrained environments, local AI systems, and edge intelligence deployment.
Technical Reports, Benchmarks & Architecture Notes
Explore SemKV architecture, benchmark evaluations, API references, and deployment-focused technical documentation.
SemKV™ Technical Overview
High-level overview of the SemKV architecture, selective semantic activation, and infrastructure design.
Benchmark & Evaluation Report
Latency, token reduction, semantic similarity, and rerank comparison benchmarks across real workloads.
Edge Compatibility Notes
CPU deployment analysis and infrastructure suitability for edge AI and constrained compute environments.
TruthMetrics™ Report
10-dimensional behavioral evaluation framework for measuring retrieval integrity, semantic fidelity, corruption visibility, and entropy survivability in enterprise AI and RAG systems.
API Quickstart Guide
Endpoint overview, compose workflow, request/response examples, and integration basics.
Context Optimization APIs for Intelligent AI Systems
Compose optimized context before inference using SemKV™ APIs built for scalable AI pipelines.
Compose optimized semantic context for LLM inference.
Measure reduction, semantic similarity, and optimization quality.
Tune optimization behavior for coverage, precision, or balanced retrieval.
Building the Next Layer of Semantic Infrastructure
SemKV™ is part of QUEBIUM's broader vision for scalable, selective, and infrastructure-native AI systems designed for intelligent retrieval, token efficiency,edge deployment, and semantic orchestration.
We are actively exploring collaborations across AI infrastructure, semantic systems, retrieval engineering, and edge intelligence.
Semantic Selection Infrastructure for Intelligent Systems